When business leaders evaluate IT Support Services, conversations frequently collapse into a simple counting exercise: how many tickets were opened, how many were closed, and did response times meet a broad contractual Service Level Agreement (SLA)?
Yet ticket volume rarely tells the true story of operational health. A help desk can close hundreds of tickets a day while end users remain quietly frustrated by recurring login errors, cumbersome VPN handshakes, and multi-day waits for replacement hardware. When employees spend an hour navigating broken multi-factor authentication (MFA) prompts or wrestling with configuration drift on a home network, business momentum stalls.
Building an IT support operation that respects user time and safeguards productivity requires structured escalation tiers, strict ticket hygiene, active knowledge curation, and purposeful mitigation of hybrid workplace friction.
The Anatomy of Structured Tiered Support
Without a structured escalation model, support desks suffer from two operational pathologies: senior engineers getting bogged down resetting routine passwords, or entry-level technicians sitting on complex infrastructure incidents while SLAs expire.
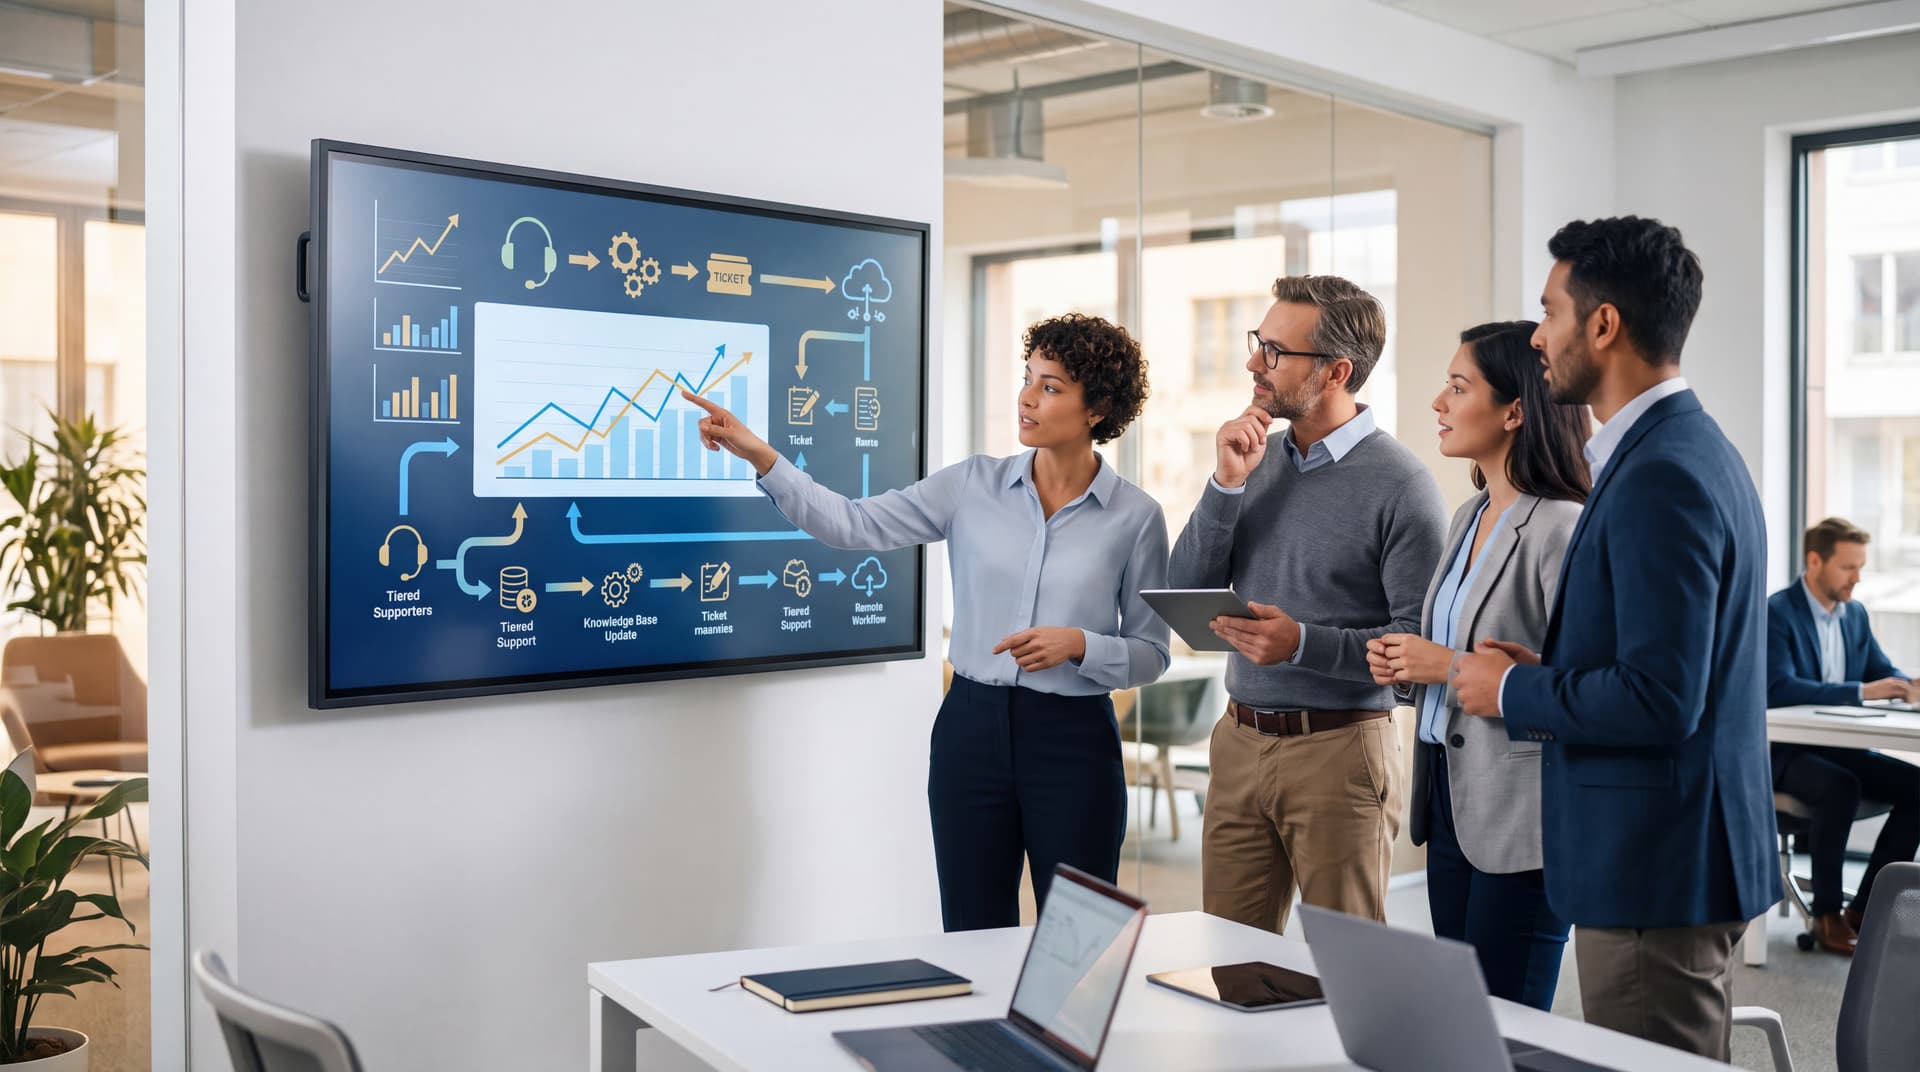
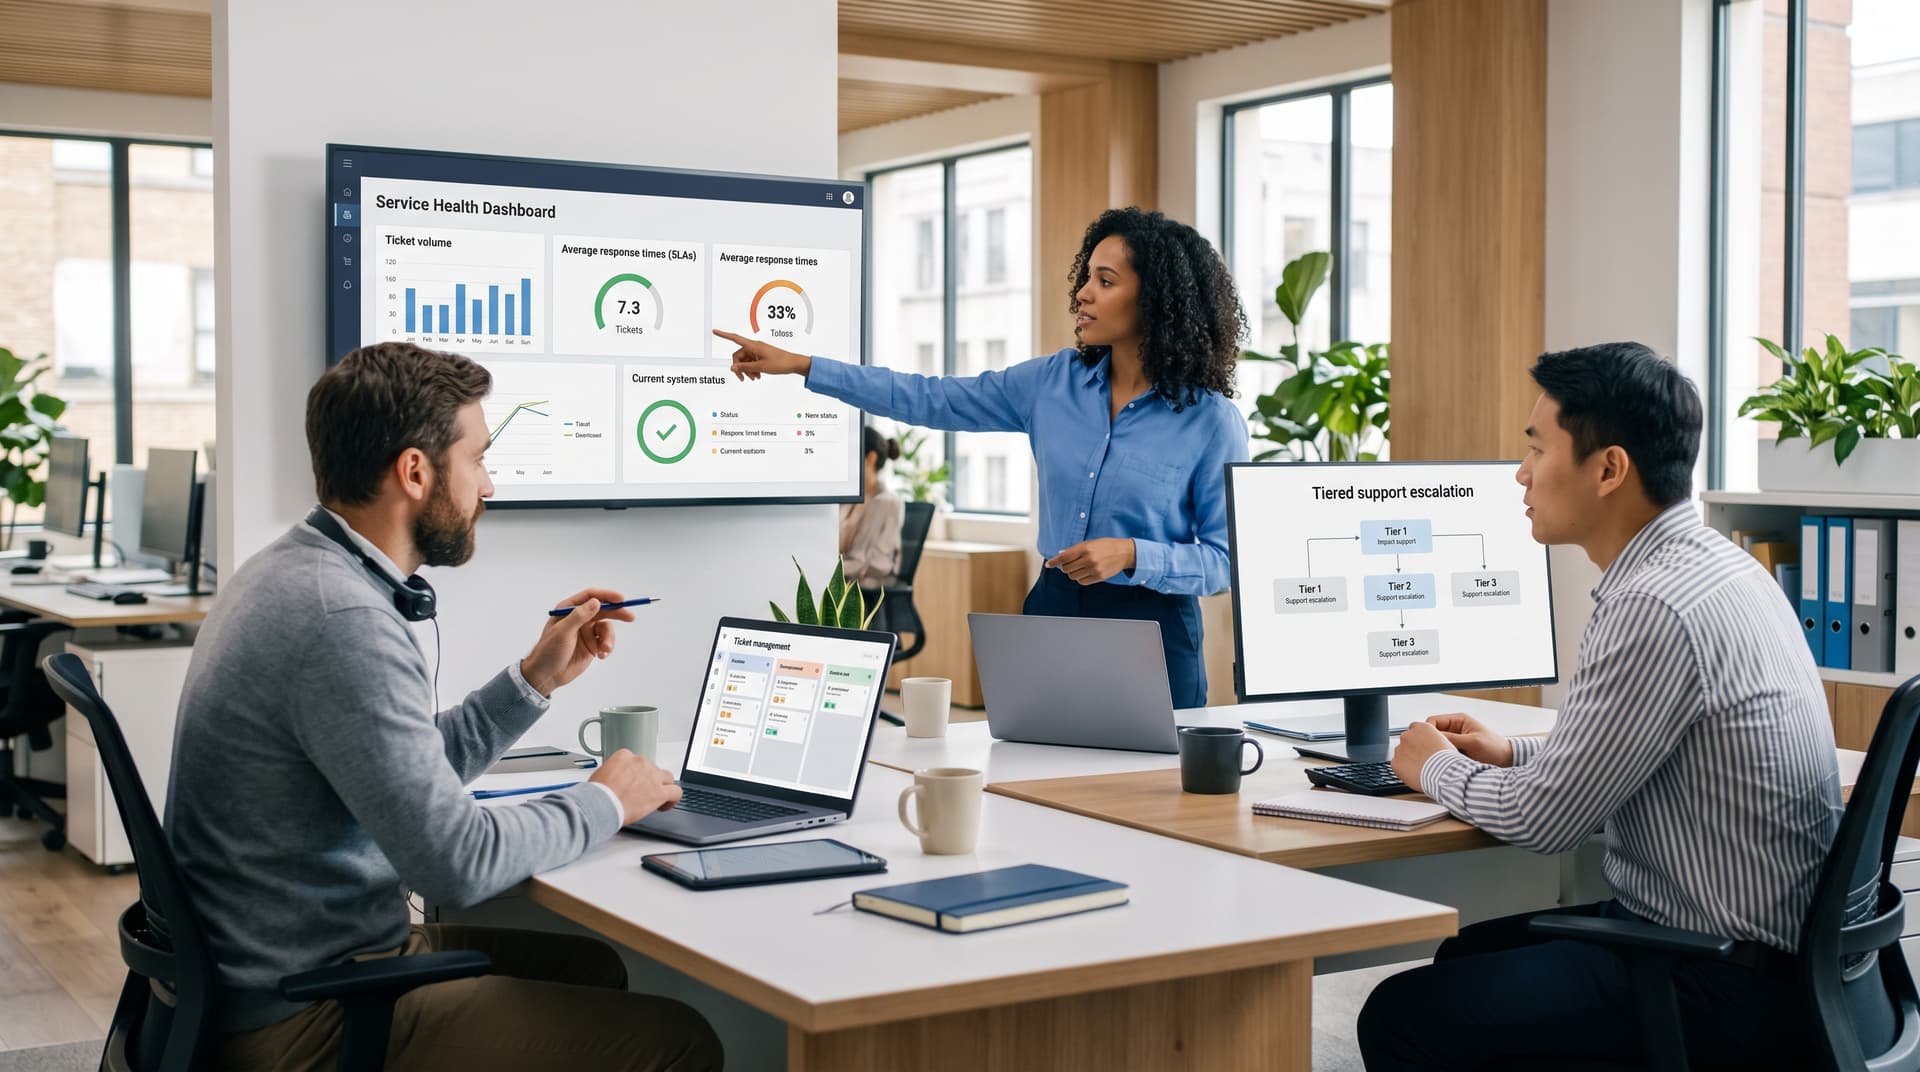
An effective tiered model aligns technician capability with incident severity and technical complexity.
+-------------------------------------------------------------+
| Tier 1: Intake, Triage & Rapid Resolution                   |
| - Identity verifications, password/MFA resets               |
| - Standard desktop & peripheral troubleshooting             |
| - Known-fix application bugs and local software reboots    |
+-------------------------------------------------------------+
                               |
                               v
+-------------------------------------------------------------+
| Tier 2: Advanced Systems & Technical Specialization         |
| - OS corruption, profile rebuilds, policy-driven config     |
| - Intermittent VPN/networking drops and driver conflicts    |
| - Advanced SaaS/M365 integration errors                     |
+-------------------------------------------------------------+
                               |
                               v
+-------------------------------------------------------------+
| Tier 3: Infrastructure, Network & Root Cause Architecture   |
| - Identity federation, conditional access policy errors     |
| - Core firewall routing, cloud directory outages           |
| - Chronic hardware defects and fleet-wide rollbacks         |
+-------------------------------------------------------------+
Tier 1: Intake, Verification, and Rapid Remediation
Tier 1 technicians act as the initial human touchpoint. Their core mandate is rapid triage, rigorous identity verification, and resolving high-frequency, well-documented issues. When equipped with clear documentation, Tier 1 should resolve standard identity challenges, browser configuration errors, local printer spooler hang-ups, and basic workstation software anomalies during the initial contact.
Tier 2: Systems, Deep Configurations, and Application Logic
When an issue cannot be resolved via documented remediation scripts within a defined window (such as 15 to 20 minutes), it must escalate directly to Tier 2. Tier 2 engineers possess specialized systems administration skills. They diagnose endpoint registry issues, investigate local operating system corruptions, resolve complicated mailbox permissions, and trace software compatibility issues without forcing the end user to re-explain their problem from scratch.
Tier 3: Infrastructure, Security, and Architecture Escalation
Tier 3 comprises senior systems engineers and network administrators. They handle systemic problems: identity provider outages, conditional access misconfigurations, chronic VPN gateway latency, or zero-day patch rollouts that fail fleet-wide. Tier 3 rarely interfaces with daily ad-hoc requests; instead, they focus on structural stabilization, recurring incident remediation, and feeding operational insights back to the organization.
Takeaway: Clear escalation boundaries protect senior engineering hours for architectural resilience while guaranteeing that end users receive immediate, focused attention for everyday operational blockers.
Operational Discipline: Ticket Hygiene and Knowledge Base Habits
A service desk is only as good as its operational data. When support staff treat ticketing systems simply as time-logging software rather than diagnostic registries, the business loses all visibility into systemic technical debt.
What Healthy Ticket Hygiene Looks Like
Ticket hygiene is the consistent application of standards to every service interaction:
- Granular Categorization: Tickets should not simply be labeled "Hardware" or "Software." They require primary categories, subcategories, and symptom classifications (e.g.,
Identity > MFA > Token De-synchronization). - Reproduction Artifacts: Technicians must record operating system builds, exact error codes, diagnostic log snippets, and network telemetry before applying a fix.
- Clear Audit Trails: Escalation notes must explain what has been attempted, what hypothesis was disproven, and why the ticket is being routed to the next tier.
- Meaningful Closure Summaries: Rather than marking a ticket as "Resolved," technicians must record the specific root cause and remediation method.
The Living Knowledge Base (KB)
Documentation cannot remain a stagnant annual project; it must be an ongoing operational habit. Mature teams practice "Knowledge-Centered Service" principles, integrating documentation into the ticket lifecycle:
- Reuse: Technicians first search internal KB articles for existing solutions.
- Flag: If an existing article contains outdated instructions or deprecated software steps, the technician flags it immediately.
- Add: If an issue requires more than 20 minutes of diagnostic research and lacks a corresponding guide, creating an initial draft article is part of the ticket closure checklist.
Eliminating Hybrid Work Friction
In a distributed or hybrid business model, technical friction directly erodes workforce trust. Remote workers cannot walk over to an office "IT closet" when their workstation fails. Support teams must intentionally redesign three traditional friction points: VPN instability, MFA recovery, and device provisioning.
| Hybrid Friction Point | Traditional Approach | Modern Service Desk Approach |
|---|---|---|
| Remote Connectivity & VPN | Full-tunnel VPN backhauling all traffic through headquarters; manual reconnects upon latency spikes. | Split-tunnel architectures or secure access service edge (SASE) routing business tools safely while bypassing streaming/general traffic. |
| MFA Resets & Identity Lockouts | Unverified phone calls or informal manager chats; hours of downtime awaiting secondary approvals. | Cryptographically validated out-of-band verification workflows that confirm identity quickly without compromising zero-trust baselines. |
| Hardware Deployment & Onboarding | Central IT office images bare-metal laptops manually; ships bulk equipment via delayed parcel services. | Zero-touch cloud provisioning (e.g., Windows Autopilot, Apple Business Manager) shipping sealed devices directly from OEM to employee. |
1. Modernizing Network Connectivity
Traditional VPN implementations that tunnel all traffic through on-premises corporate firewalls create massive bandwidth bottlenecks for remote teams accessing cloud-hosted applications. IT support teams should actively identify when connectivity tickets stem from misconfigured routing, advocating for split-tunnel setups or modern zero-trust network access that secures corporate resources without choking productivity.
2. Streamlined Yet Secure MFA Verification
Account takeovers frequently exploit support desks via social engineering. When an employee loses their phone or resets their authenticator app, Tier 1 technicians face competing pressures: speed versus security. The solution is not looser security policies, but clear, automated out-of-band identity checks (such as manager video-verification or temporary one-time bypass keys distributed via verified HR mechanisms) that eliminate day-long identity lockouts.
3. Zero-Touch Provisioning Over Manual Imaging
Manual device imaging is one of the largest drains on internal IT resources and a common source of onboarding delays. By adopting cloud-native configuration management, SMBs ship factory-sealed hardware straight to a new employee's home. The moment the user logs in with their corporate credentials, enterprise policies, security baselines, and business applications install automatically.
Measuring Support Quality Beyond Ticket Volume
Evaluating IT support purely by counting resolved tickets incentivizes the wrong behavior. Technicians rush through superficial fixes to "close" tickets, leaving underlying issues untouched and forcing users to open secondary requests days later.
To gauge true end-user experience, business leaders should track qualitative operational metrics alongside velocity:
- First Contact Resolution (FCR): The percentage of incidents completely remediated during the initial user interaction. High FCR indicates capable Tier 1 technicians and authoritative knowledge documentation.
- Reopen Rate: The frequency with which "resolved" tickets are reopened by users within 7 to 14 days. A high reopen rate points to superficial symptom-treating rather than effective root-cause remediation.
- Time to First Meaningful Response: Moving beyond automated auto-replies, this measures how quickly an engineer analyzes the ticket and provides actionable technical guidance.
- Escalation Churn: The number of technician handoffs a ticket undergoes before reaching resolution. Every handoff introduces latency and user fatigue.
- Net User Sentiment: Brief, post-resolution surveys that measure perceived friction rather than technical compliance. Questions should assess whether the interaction made the employee's work day easier.
By monitoring these indicators on executive dashboards, leadership gains clear insight into technical stability, team morale, and organizational velocity.
Transforming Support from a Cost Center to an Operational Lever
When managed properly, an IT support desk does far more than reset passwords. It serves as an early warning detection network for software misconfigurations, security vulnerabilities, and workflow bottlenecks.
By organizing support into clear escalation tiers, maintaining uncompromising ticket hygiene, curating active knowledge bases, and systematically dismantling hybrid work friction, growing SMBs turn their service desk into an engine of everyday workforce productivity.
See how Bitscaled structures help desk tiers, SLAs, and executive reporting by visiting our IT Support Services page or exploring our operational toolsets on the Bitscaled Platform.