Rethinking Help Desk Operations: Friction-Free Hybrid Support and Meaningful Service Metrics
When employees reach out to an internal IT help desk, they are rarely interested in internal operational mechanics. They are dealing with a barrier between themselves and their core responsibilities. An uncooperative multi-factor authentication prompt, an unstable VPN tunnel, or an onboarding laptop delayed in transit does more than generate a ticket—it stalls customer deliverables, erodes employee morale, and consumes executive focus.
For small to mid-sized businesses (SMBs), measuring support success purely through raw ticket volume or superficial close times creates a false sense of security. A team that closes eighty tickets a day might simply be cycling through repetitive, low-impact workarounds while structural productivity bottlenecks remain unaddressed.
Modern IT support services require an intentional operational framework: clearly delineated escalation tiers, strict ticket hygiene, living knowledge bases, and metrics that measure user sentiment and operational recovery rather than mere transactional throughput.
Structuring Tiered Escalation to Eliminate Choke Points
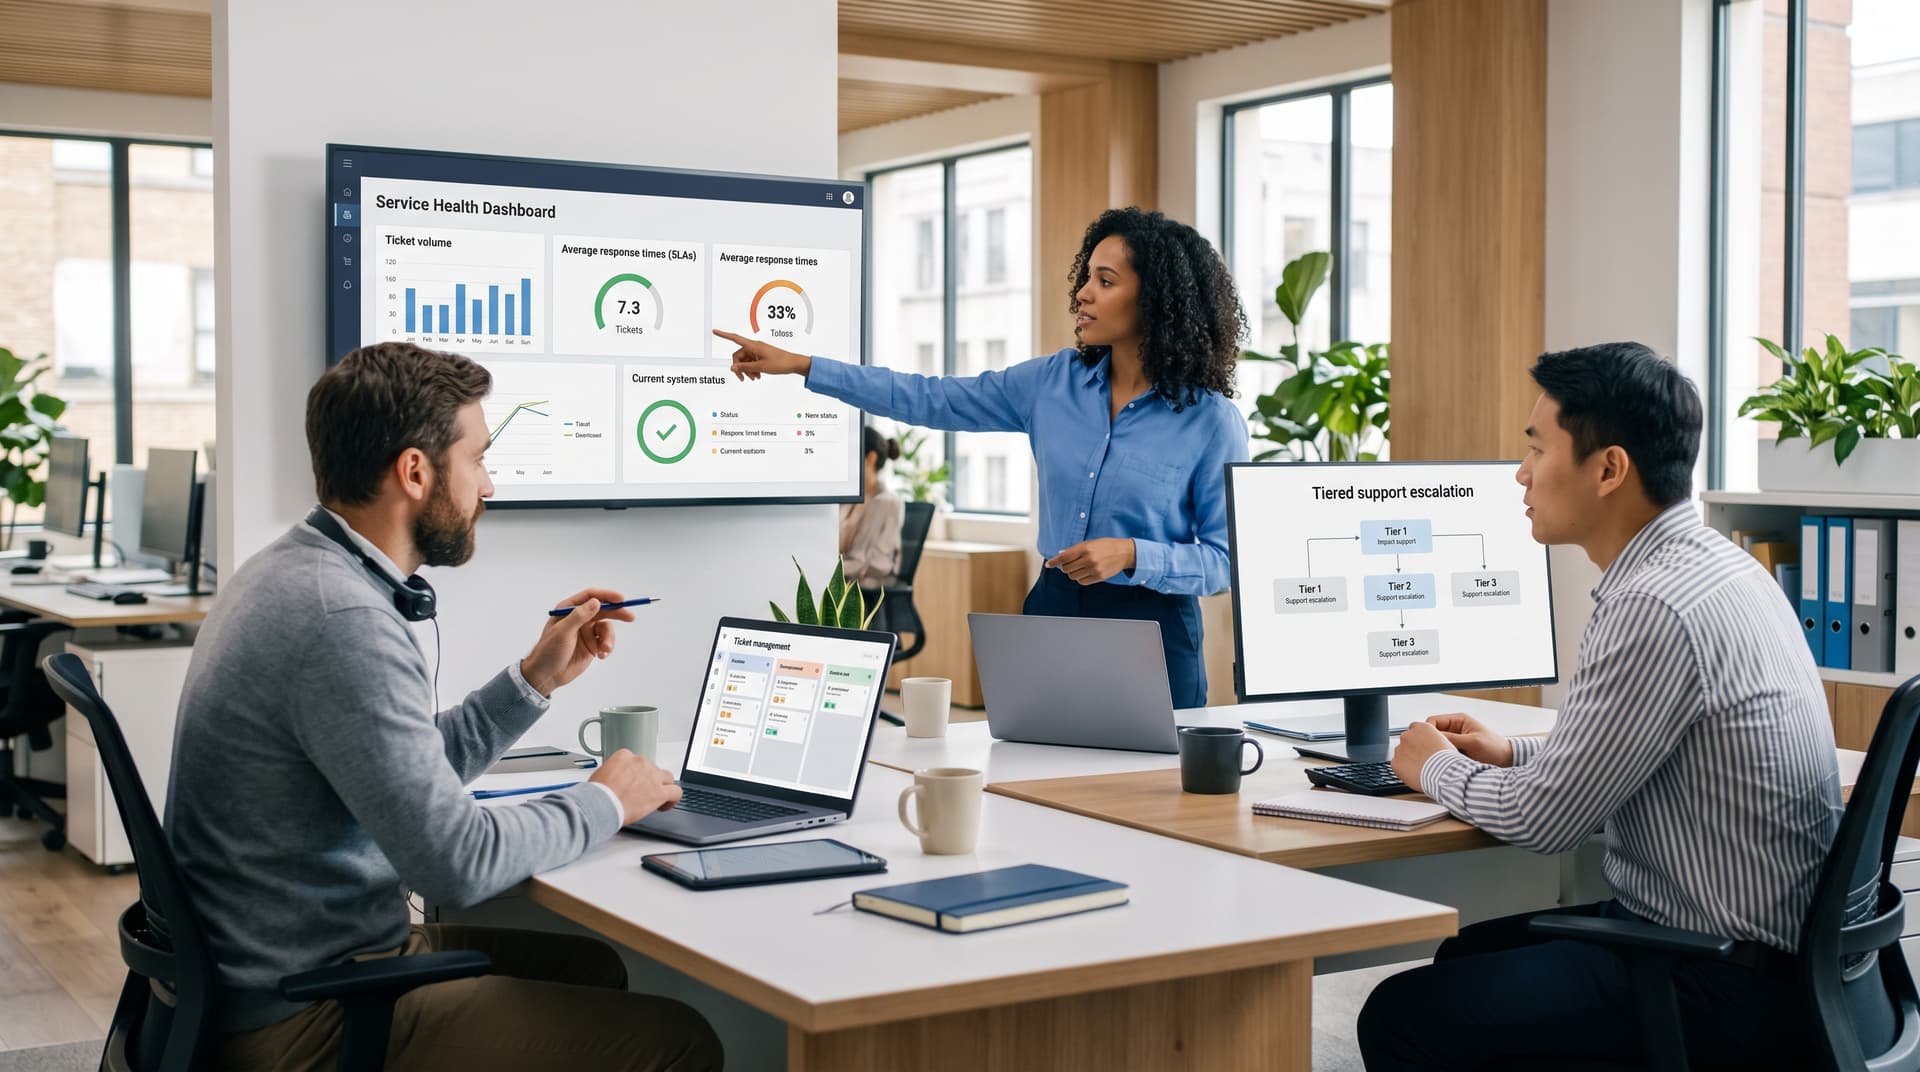
Without a structured escalation model, technical requests default to an ad-hoc queue where urgent operational blockers compete directly with routine administration tasks. Tiering brings order by defining explicit scope, escalation thresholds, and ownership boundaries across the service organization.
Tier 1: Front-Line Triage and Rapid Resolution
Tier 1 acts as the primary point of contact across chat, email, or portal channels. The primary objective is not complex diagnosis, but fast triage, identity verification, and resolution of documented operational tasks:
- Password synchronization and identity resets.
- Standard application access provisioning.
- Basic hardware diagnostics and peripheral troubleshooting.
- Ticket classification, user context capture, and initial priority labeling.
When Tier 1 possesses comprehensive procedural documentation, the majority of day-to-day administrative requests are resolved on first touch, preventing operational backlogs downstream.
Tier 2: Advanced Systems and Configuration Support
Tier 2 specialists handle non-standard configurations, systemic application crashes, workstation driver conflicts, and intermittent network issues. They receive escalations when initial runbooks fail to yield a resolution within defined time windows—typically 15 to 30 minutes of active troubleshooting. Tier 2 engineers also identify recurring trends and draft standard operating procedures for Tier 1 implementation.
Tier 3: Specialized Infrastructure and Engineering
Tier 3 comprises senior system administrators, cloud engineers, and network architects. These individuals focus on structural platform stability, identity directory federation, software distribution packaging, and complex incident remediation. Keeping Tier 3 shielded from direct end-user queues ensures that strategic infrastructure initiatives and major incident interventions proceed without constant context switching.
Takeaway: Clear tiering is not about adding bureaucracy; it prevents senior engineers from acting as expensive password-reset desks while ensuring urgent end-user issues receive rapid frontline attention.
The Disciplines of Ticket Hygiene and Knowledge Base Management
A service desk cannot function effectively on memory and informal chat logs. Maintaining rigorous ticket hygiene and active documentation habits transforms daily support interactions into institutional knowledge.
Essential Ticket Hygiene Habits
Every incident or request must maintain standardized data integrity from creation to closure:
| Operational Field | Purpose | Common Anti-Pattern |
|---|---|---|
| Classification & Category | Identifies underlying system or service | Defaulting everything to "General IT" or "Email" |
| Root Cause Coding | Captures whether the failure was user education, bug, or outage | Closing tickets with generic "Fixed" notes |
| Impact vs. Urgency | Establishes objective priority over subjective user panic | Treating every senior leader request as Priority 1 |
| Work Log Specificity | Documents specific steps taken for future cross-tier handoffs | Leaving blank notes or cryptic single-word logs |
| Asset Association | Ties the issue to a specific device serial or cloud identity | Troubleshooting hardware blind to device maintenance history |
Treating the Knowledge Base as a Living System
Documentation frequently deteriorates when treated as an occasional administrative chore rather than an integrated troubleshooting step. High-performing help desks integrate knowledge creation directly into the ticket resolution workflow:
- Zero-Result Logging: Identify what end users search for in the self-service portal that yields zero results, flagging immediate candidates for new articles.
- Runbook Ownership: Every runbook carries an assigned engineering owner and a mandatory review cycle.
- Inline Updates: If a technician discovers an outdated screenshot, command, or workflow during a call, the resolution of that ticket requires updating the article before closing the loop.
- Dual-Facing Content: Maintain user-facing guidance written in clean, empathetic, non-technical language alongside technical runbooks detailing backend administrative steps.
Resolving Hybrid Work Friction Points
Distributed and hybrid operations have changed the nature of IT support. End users are no longer sitting behind an enterprise perimeter firewall with local technicians walking the floor. Instead, three distinct bottlenecks account for an overwhelming share of remote worker dissatisfaction.
1. Multi-Factor Authentication (MFA) Resets and Identity Lockouts
When an employee loses access to their primary authentication device, productivity halts completely. Remote environments cannot rely on physical hallway verification, leaving organizations caught between security risk and user downtime.
- Empathetic Operations: Establish verified identity challenge workflows that do not require employees to wait hours for manual intervention.
- Preventative Architecture: Encourage redundant enrollment of authentication mechanisms (such as hardware tokens or secondary corporate devices) during onboarding to ensure fallback options exist.
2. VPN Instability and Intermittent Network Latency
Remote workers regularly encounter dropped VPN tunnels, split-tunnel routing misconfigurations, and severe bandwidth throttling on residential internet connections. Telling a user to "restart their home router" without technical investigation creates immediate frustration.
- Modern Remediation: Transition away from legacy, all-traffic tunnel VPN architectures toward identity-aware Zero Trust Network Access (ZTNA) or optimized split-tunneling where only sensitive corporate resources route across secure gateways.
- Diagnostics: Implement endpoint telemetry that lets support staff quickly isolate whether packet loss occurs on the residential Wi-Fi, the ISP link, or the corporate VPN concentrator.
3. Remote Device Provisioning and Hardware Replacement Delays
Nothing damages an employee's first week more than staring at a tracking number or receiving a laptop that requires three hours of administrative elevation over the phone to configure basic software.
- Zero-Touch Provisioning: Leverage cloud endpoint management frameworks where pre-configured profiles, security policies, and software packages deploy automatically upon the first network handshake.
- Logistics Buffering: Maintain a small, hot-standby pool of pre-enrolled hardware ready to ship same-day in the event of hardware failure, minimizing end-user downtime from days to hours.
Measuring Support Quality Beyond Ticket Volume
Traditional service desk metrics often incentivize the wrong behaviors. If a help desk is graded solely on "Tickets Closed per Day" or "Average Handle Time," technicians are implicitly rewarded for rushing users off the phone, deferring complex problems, or encouraging users to open separate tickets for related issues.
SMB leadership must pivot to balanced metrics that reflect service stability, user empathy, and engineering efficacy.
Critical Performance Indicators
- First-Contact Resolution (FCR): The percentage of incoming issues fully resolved during the initial contact without requiring reassignment or subsequent follow-up. High FCR indicates competent frontline triage and accessible documentation.
- Reopen Rate: The proportion of resolved tickets reopened within 48 to 72 hours. A rising reopen rate reveals incomplete fixes and technicians rushing to meet volume quotas.
- Customer Effort Score (CES): Rather than asking generic satisfaction questions, CES evaluates how straightforward it was for the employee to get help. High effort indicates fragmented communication or confusing escalation portals.
- Mean Time to Productivity (MTTP): Shifting focus from "Mean Time to Close" to the exact timeframe required to restore the user's ability to work, acknowledging that an open ticket for a temporary hardware loaner still restores active output.
Illustrative Quality Balanced Scorecard
| Quality Indicator | Focus Area | Operational Target (Illustrative) | Strategic Value |
|---|---|---|---|
| First-Contact Resolution | Frontline capability | > 70% of standard requests | Maximizes employee uptime; prevents Tier 2 backlogs |
| Ticket Reopen Rate | Resolution durability | < 5% across closed incidents | Verifies thoroughness over hasty ticket closure |
| SLA Attainment | Service reliability | > 95% on initial response and recovery | Sets predictable operational expectations across departments |
| CSAT / Sentiment | User empathy | > 92% positive sentiment | Captures the human side of technical support interactions |
Partnering for Resilient, User-First IT Support
Building an internal, round-the-clock help desk with complete three-tier coverage is frequently cost-prohibitive for growing mid-sized organizations. As organizations scale, technical leadership often spends more time managing queue surges and on-call schedules than focusing on strategic business initiatives.
By leveraging structured IT support services alongside ongoing managed infrastructure services, SMBs gain access to enterprise-grade escalation workflows, modern endpoint management tooling, and predictable service levels without the operational overhead of running a dedicated support facility.
See how Bitscaled structures help desk tiers, SLAs, and executive reporting to eliminate workplace friction and keep your teams focused on growth. Connect with our engineering team through our contact page or review our service models at Bitscaled Support Solutions.